80% of RAG Problems Start in Document Parsing
The AI-FDE Transition Path · AI Engineering 05 — Document Parsing
1. Garbage In, Garbage Out — No Model Can Fix It
This article is for implementation, pre-sales, and operations people working on enterprise knowledge bases and RAG over policies, contracts, and manuals. It does not discuss model selection or fine-tuning. The parameters and thresholds here are starting points, not promises — you must calibrate them by sampling on each project.
My view: document parsing is the segment of the entire RAG pipeline with the highest return on effort — and the one nobody wants to do.
At the end of the last lecture I said that after grouping issues by pipeline stage, most of them land in parsing and chunking. This lecture covers the first of those two.
Here's the counterintuitive part: this segment has almost no technical depth, yet it sets the ceiling on final quality. It's grunt work, not clever work. That's why nobody likes doing it — and it doesn't make a good weekly report either, not like "we switched to a bigger model." But this is the segment that decides whether the project lives or dies.
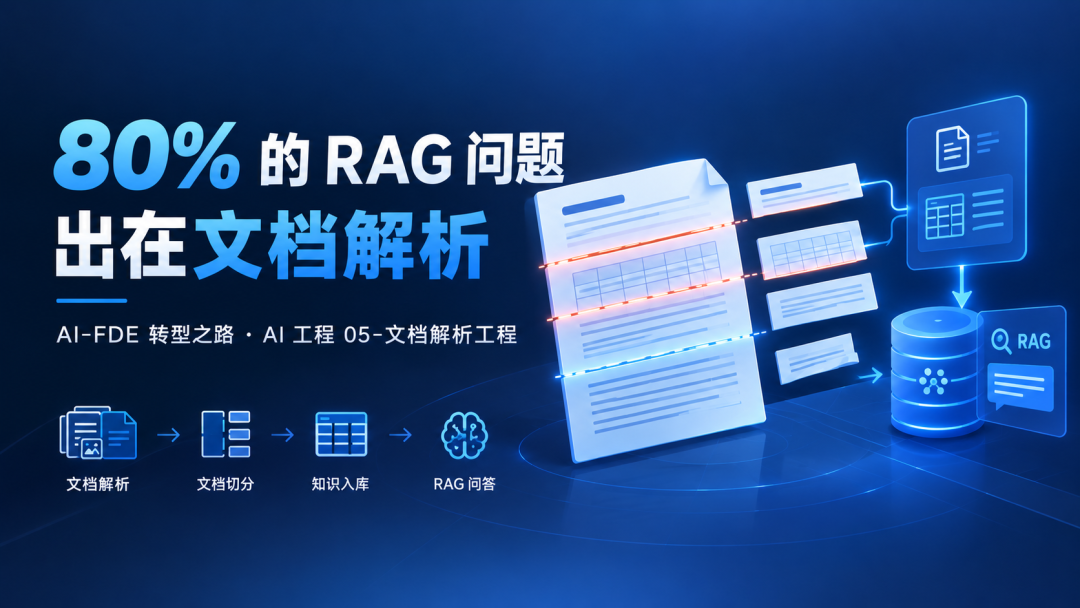
2. The Four Killers
Here's an analogy. You ask a chef to cook a dish, and you supply the ingredients. He doesn't recognize this batch of vegetables, and you haven't washed or chopped them—you just throw the whole muddy head into the pot, then judge, "This chef isn't up to standard." That's unreasonable, but this exact scenario plays out at client sites every day.
Before documents make it into the knowledge base, they die at the hands of these four types:
Type one: Scanned files. Image-based PDFs, where each page is actually a picture and must go through recognition to produce text. This recognition step is exceptionally good at reading "Article 3.2" as "Article 3.2 Kill," "5 million" as "5 square," and the code "ZX07" as "ZX0T." The errors are extremely specific, and silent—you won't find them unless you check against the original.
How to spot: Try to select a passage of text in the PDF; if you can't select it, it's an image. Then pull 3 pages and check whether codes, amounts, and dates are readable.
How to fix: Run OCR on these pages separately; after recognition, use regex spot-checks on article numbers, amounts, and dates, and flag pages with many errors for manual review.
What acceptance looks like: Sample 10 key fields; codes/amounts/dates are readable and match the original, and the error rate drops to an acceptable range.
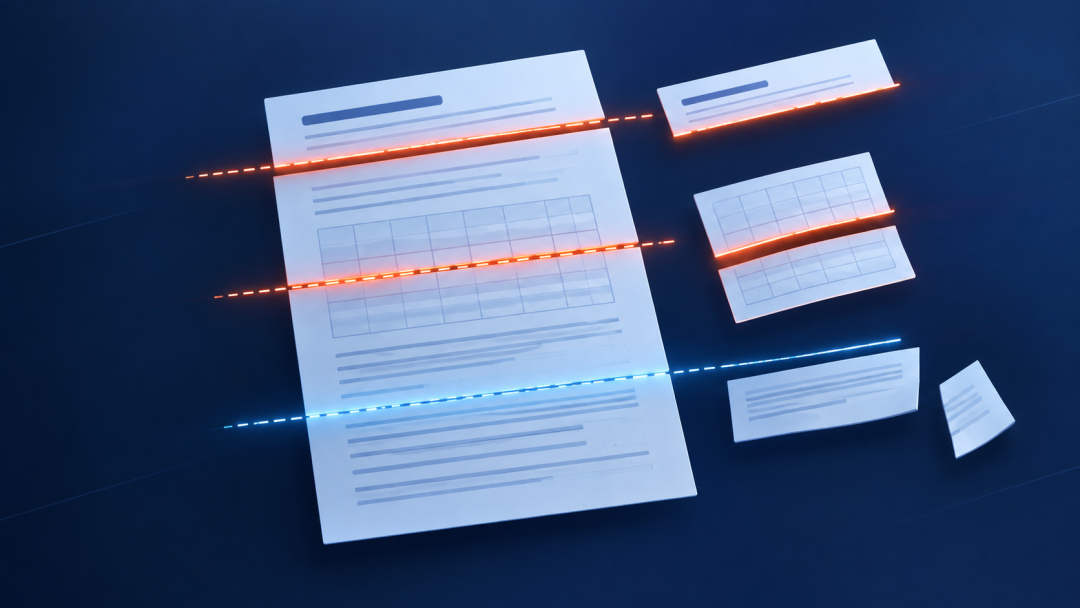
Type two: Tables. Tables are the things most easily "physically broken." A thirty-row table gets sliced down the middle during chunking—the top half in chunk A, the bottom half in chunk B, and the header only in A. So whenever B is retrieved, the model sees a string of numbers with no column names. It answers wrong not because it's dumb, but because it can't see the header.
How to spot: Find a long table that spans pages and check whether the header follows each chunk.
How to fix: Preserve table structure during parsing and convert it to table markup—don't flatten the table into rows of text; for cross-page tables, backfill the header into every chunk.
What acceptance looks like: Sample a cross-page table; every chunk shows the column names, and no chunk appears with "only numbers, no header."
Type three: Multi-column layout. For two-column documents, many parsers read by physical line, so a sentence from the left column and a sentence from the right column alternate—it reads like two people talking past each other. Multi-column layouts are common in policies and contracts.
How to spot: Find a passage of two-column content and check whether the sentences are coherent, whether you get a crossover like "the previous sentence is about credit approval, the next about the cafeteria."
How to fix: Switch to a parser with layout coordinates and reorder by reading order—left column first, then right; after the change, sample three passages and read them to check for smoothness.
What acceptance looks like: Sample three passages of two-column content; they read as one continuous passage, not a left-right alternating "conversation across the void."
Type four: Heading hierarchy. This one is the most hidden. A passage belongs to "Chapter 3 / Section 2 / Article 3.2 / Notes"—this hierarchical relationship is expressed in the original document through font size and indentation, and after parsing it may all become one line of flat text. Once the hierarchy is lost, the model doesn't know where the applicable boundary of this passage lies—and for policies, the applicable boundary is almost everything.
How to spot: Check whether chunks carry "Chapter X, Article Y," or whether they're all bare text with no discernible sense of belonging.
How to fix: Record the heading path during chunking, concatenate it into a prefix and stuff it into the chunk, or preserve the parent heading as metadata.
What acceptance looks like: Sample any three chunks; each one's beginning shows "which chapter and article it belongs to."
How to fix these four types—the right-hand column of the table in Section IV gives the method item by item. But before fixing, there's something more important to discuss first—chunking.
3. How to Split: Choose the Right Mode First, Then Tune Parameters
First, let's correct a common misconception: splitting is not an aesthetic question of "how fine to cut," but a question of "what boundary to cut along."
An analogy. To break a policy document into cards, there are two approaches: one ignores content and cuts every 500 characters; the other cuts by "article," one card per article. The former is easier, but often cuts an article in half and glues two articles together; the latter is slower, but every card is a complete article.
| Approach | How to split | What it suits | Cost |
|---|---|---|---|
| Fixed length | Cut by character or token count, with overlap | Documents with no inherent structure (meeting minutes, emails, chat logs) | Prone to cutting mid-sentence or mid-table |
| By structure | Cut along heading / clause / paragraph boundaries | Policies, contracts, manuals—things with numbering and hierarchy | Must be able to recognize the structure first; pure scanned images won't work |
| By semantics | Merge adjacent paragraphs with similar meaning into one block | Material with no hard structure and mixed content | Requires an extra model run—cost and latency |
My recommendation: for financial documents, default to the "by structure" mode. Policies and contracts inherently have numbering—"Article 3.2" is a ready-made boundary, and cutting by character count actually destroys it.
Once the mode is right, then it's time for parameters. Here's a set of starting points for three parameters (suggested baseline, to be calibrated per project, not a commitment):
| Parameter | Suggested baseline | Why |
|---|---|---|
| Chunk size | 300–800 characters (or 500–1000 tokens) | Too small loses context; too large scatters retrieval |
| Overlap | 10%–20% of chunk length | Keeps sentences at boundaries from being cut off |
| Hard cap | Force re-split beyond 1500 characters | Any larger exceeds the scope of "one meaning" |
But more effective than tuning parameters are these two moves.
Move one: give every chunk a "provenance prefix." The chunks you cut out are bare; just prepend "Chapter 3 / Section 2 / Article 3.2" to each, and it gains belonging. When a retrieval hit comes back, the model sees a passage with its source, not a sentence that appeared out of nowhere. This move costs nothing, and its effect is usually more obvious than fiddling with parameters for ages.
Move two: retrieve with small chunks, feed the model large chunks. During retrieval, search by small chunk—accurate; after finding it, don't hand that small block to the model, but pass along the entire section it belongs to—complete view. The industry calls this "small-to-big retrieval." Most document-oriented scenarios should do this; this one move alone rescues many "right answer but can't state the source" problems.
4. A Checkup Sheet: Half for Diagnosis, Half for Treatment
This is the thing I took away with me, and it's the page from this article that most deserves to be printed out. Pull twenty representative documents and go through them one by one, note down where they're bad, and the right-hand column tells you directly how to fix it (the example counts are just to illustrate the method—calibrate to your own project):
| Check item | How to check | What failing looks like | How to fix |
|---|---|---|---|
| Is it a scanned document | Try selecting a passage of text in the PDF; if you can't select it, it's an image | The whole thing is selectable, but a few image pages are mixed in | Run those pages through recognition separately; after recognition, spot-check with regex on clause numbers, amounts, and dates, and flag pages with a high error rate for manual review |
| Are numbers misrecognized | Sample ten clause numbers and compare them character by character against the paper/image original | Letter O mixed up with digit 0, 1 mixed up with l | Don't expect general-purpose recognition to be fully correct. Do targeted validation only on key fields: clause numbers, amounts, dates—these three, because errors there cause real trouble |
| Are tables still intact | Find a long table that spans pages and see whether the header follows each segment | Only the first page has column names | Preserve table structure during parsing (convert to table markup); don't flatten tables into rows of text; for tables spanning pages, backfill the header into every segment |
| Are multi-column layouts mixed up | Find a section of two-column content and see whether the sentences are coherent | The previous sentence is about credit approval, the next is about the cafeteria | Switch to parsing with layout coordinates and reorder by reading order (left column first, then right); after fixing, sample three passages and read them to check they flow |
| Are heading levels present | See whether a chunk can carry "Chapter X, Article Y" | All bare text, no way to tell what it belongs to | Record the heading path when chunking, assemble it into a prefix, and stuff it into the chunk (that's the first trick from the previous section) |
| Are headers and footers cleaned out | Search for a common header word and see how many hits you get | Every page has the company letterhead and page number mixed in | Deduplicate by position (remove repeated content at the same position on each page); don't delete by keyword—keywords will hit body text by mistake |
| Are chunk boundaries reasonable | Sample ten chunks and see whether the start is half a sentence | Most chunks start mid-sentence | Stop fiddling with character counts; switch to "structure-based" chunking (the second tier from the previous section) |
Of the seven, I think three must be checked first: scanned documents, tables, and heading levels. If these three are broken, no amount of tuning later will save it. The other four make the results a bit better; these three make the results possible at all.
5. Dify/Tool Implementation Mapping
The tool is not the point; the point is whether every action has a corresponding acceptance checkpoint in the tool. This applies to Dify, and to any other tool as well. The table below is a mapping of "what to ask, where to configure" during implementation—not written as a tutorial:
| Article Action | Corresponding Entry Point in Dify | Notes |
|---|---|---|
| Scanned/complex PDF parsing | Knowledge Pipeline connected to parsing plugins like MinerU, LlamaParse; or external knowledge base | Don't rely on the default extractor to read images |
| Table structure preservation | Parsing plugin outputs HTML/structured markup | Check whether cross-page headers are backfilled |
| Multi-column reordering | Unstructured, Docling plugins, or RAGFlow external knowledge base | Check whether reading order is left-to-right |
| Structure-based chunking | Custom segment identifier + regex; Markdown Header | Validate regex against the original text first—don't damage body content |
| Small retrieval, large feed | Parent-child chunking mode | Select at creation; cannot be changed afterward |
| Provenance prefix | Preserve parent heading metadata / Metadata Filtering | Don't pollute body content |
| Retrieval tuning | Hybrid search + Rerank + TopK/threshold | Change the tier first, then tune parameters |
To reiterate the order: first clean up the parsing entry point, then create the knowledge base and select parent-child mode and structural anchors, then confirm metadata preservation, and only then touch TopK and thresholds. After changes, re-verify.
6. What Counts as Knowing It
You can tell your own knowledge base, "Our worst category of documents is such-and-such," and back it up with evidence (the results of a twenty-document sample check).
You can say which chunking approach you're currently using, and why it's that one—if you can't give a reason, it's probably just the default parameters that have been running all along.
You spot-check any three chunks, and at the start of each one you can see "which chapter and which section it belongs to."
When the client says "let's add some more materials," you can first ask "what format are these materials in?" instead of just taking them and parsing them right away.
You know who on the team is responsible for accepting this part—if no one is, then it's you.
One self-check question: in your knowledge base, what percentage is scanned documents? If you can't answer, chances are there's a batch of documents that has never been parsed correctly.
7. Hands-on tasks (do them in order, don't skip steps)
Pull twenty documents from the knowledge base, run them through the checklist, and sort them into three piles: "passes / barely usable / must be redone." If the last pile exceeds 20% (an example threshold, used here only to illustrate the approach), don't move on to the later optimizations — go back and re-parse first.
Output: the checklist + the three-pile list.
Answer one sentence: "Which chunking approach am I currently using?" If the documents have numbering and you're using fixed-length chunking, redo it with structure-based chunking and run the same ten questions against it — change the approach first, then tune parameters.
Output: a one-sentence statement + a before/after 10-question comparison table.
Grab three chunks at random and check whether the beginning contains "Chapter X, Section Y." If not, prepend the heading path — this is the cheapest fix in this article.
Output: screenshots or text of the 3 chunks, with "Chapter X, Section Y" added.
After fixing, run the checklist again. If you don't re-check after fixing, it's as good as not fixing at all.
Output: the re-check checklist, with the items that got worse marked.
A change without a re-check record doesn't count as done; a checklist without an owner doesn't count as implemented.
8. Pitfalls
Twisting the parameters while refusing to change the chunking mode. The most common form of spinning in place: chunk size goes from 500 to 300 and then to 800, overlap goes from 10% to 30%, and results never improve. The reason is that the mode was wrong from the start — the document has numbering but is being chunked by character count, so no matter how you tune the parameters, you're just manufacturing fragments. Pick the right mode first, then talk about parameters.
Spot-checking only the electronic-version documents and assuming everything is fine. Many documents today are "semi-electronic": electronic layout at the front, a few pages of scanned signature images in the middle, electronic again at the back. Sampling must cover those scanned pages, or the health-check results will be overly optimistic.
Using manual labor to re-sort everything. I've seen teams, in order to make documents "clean," assign people to re-enter hundreds of policy documents from scratch. High cost, long cycle, and any policy change means starting over. That money is usually better spent tuning the parsing script, unless the total document count is only a few dozen.
(After changing the parsing, remember to re-check — rerun the health-check table and see whether those metrics actually came down. Changing without re-checking is the same as not changing.)
Next lecture shifts gear, from "what to feed the model" to "how to get the model to call external systems": tool descriptions are the manual written for the model to read.
"The AI-FDE Transition Path": written for IT implementation / pre-sales / operations people who don't write code, to turn existing delivery capabilities into "AI-ized" ones. 55 articles in the full series, 53 skills across six major modules.
Want to first see what you're missing: the AI-FDE Skills Self-Assessment Map, 53 items scored, producing a radar chart. The AI-FDE Transition Path · Introduction